Slow Server, Fewer Pages Indexed: The Crawl Budget Problem Nobody Mentions
Most SEO conversations focus on rankings. Backlinks, keywords, content quality, Core Web Vitals scores. The assumption underneath all of it is that Google has already read your pages.
That assumption is not always correct.
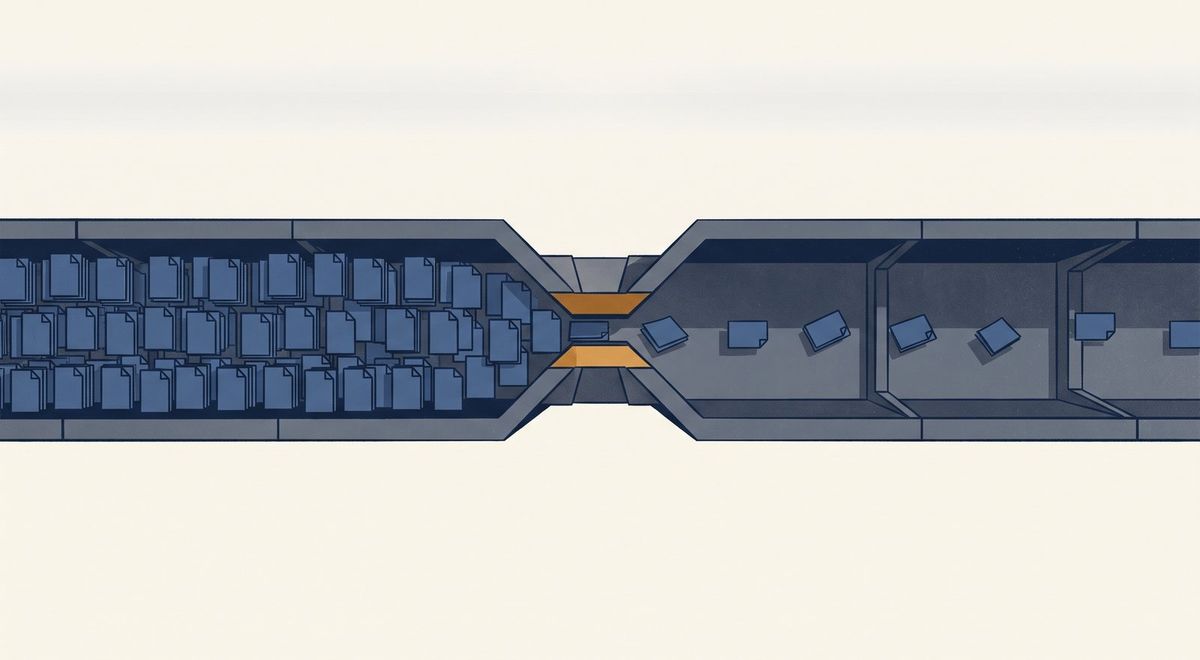
Before a page can rank, Googlebot has to crawl it. Before Googlebot crawls it, the server has to respond quickly enough that Googlebot decides to come back, and come back often. When a server is slow, Google does not just index your pages slowly. It progressively reduces the rate at which it visits your site. And for a business with 50 or 100 or 200 pages, that throttled crawl rate means a significant portion of those pages may not be getting indexed at all.
This mechanism operates entirely upstream of any ranking signal. It is not about whether Google ranks your page well. It is about whether Google reads your page in the first place.
What Google’s Own Documentation Says
Google’s Crawl Budget Management documentation, updated in 2024 and revised again in 2026, describes the relationship between server response time and crawl rate directly:
“If the site responds consistently and its response times… remain stable or improve, the limit goes up… If the site slows down… the limit goes down and Google crawls less.”
That is a direct quote from Google’s primary developer documentation, not an SEO industry interpretation. Google is explicitly stating that it adjusts how much it crawls your site based on how fast your server responds. Consistent, fast responses earn more crawl capacity. Slow or inconsistent responses earn less.
John Mueller, Google’s Search Advocate, put a specific number on it in a YouTube podcast discussion. This is a secondary-reported quote, attributed to Mueller via podcast coverage by Kwebby in 2024: “If it takes on average like three seconds to get a page from your server, that’s actually a very long time.”
Three seconds of server response time is where Google considers de-prioritizing crawl activity. That is a threshold many SMB websites are operating near or above, particularly sites on shared hosting, or WordPress installations loaded with plugins that run database queries on every page load.
Google also stated in the same documentation: “Make your pages efficient to load. If Google can load and render your pages faster, we might be able to read more content from your site.” The phrasing is measured: “might be able to”, but the connection between page efficiency and indexing volume is explicit and direct, from Google’s own developers.
The Metric That Matters Here: TTFB
The relevant server metric for crawl budget is TTFB: Time to First Byte. It measures the time between a browser (or a crawler) making a request to your server and receiving the first byte of the response. This is a server-side measurement: how long does it take your server to start sending a response at all.
TTFB is distinct from Core Web Vitals. LCP, INP, and CLS are browser-side measurements, they capture what real users experience as a page loads and they interact with it. TTFB is measured before the page loads at all: it is the moment of contact between the crawler (or visitor) and the server.
A site can have good Core Web Vitals on the front end, thanks to a CDN caching content close to users, and still have slow TTFB from its origin server. For Googlebot, which in many configurations bypasses CDN caches and hits origin servers directly, a slow origin TTFB is a direct signal that crawls should be throttled.
Google confirmed in a December 2024 Search Central Blog post that CDN usage raises Google’s crawl throttling threshold, explicitly stating that “our crawling infrastructure is designed to allow higher crawl rates on sites that are backed by a CDN.” A CDN is not just a user-experience tool, it is a crawl infrastructure tool.
Resource Crawl Budget: The Hidden Cost of Script Bloat
Google clarified in December 2024 that crawl budget is not just about HTML pages, it applies to every resource fetched during rendering.
From Google’s Search Central Blog (December 2024): “Crawling the resources needed to render a page will chip away from the crawl budget of the hostname that’s hosting the resource.”
This means every JavaScript file, every CSS stylesheet, every third-party resource your page loads during rendering consumes crawl budget, specifically, the crawl budget of whatever server is hosting that resource. A plugin-heavy WordPress site loading 40 third-party scripts is not just slow for users. It is distributing crawl budget consumption across 40 different hostnames, with each resource request contributing to how Google perceives the crawl economics of your site.
For SMBs that have added plugins and scripts incrementally over years, a live chat widget here, a review aggregator there, a booking calendar, a pop-up tool, an analytics layer, the cumulative resource load can be substantial, and its effect on indexing is not reflected in any Lighthouse score.
A Worked Example at SMB Scale
A Tampa Bay real estate brokerage has 200 listing pages, plus service area pages, neighborhood guides, and team profiles. The site runs on WordPress with a popular theme and about 22 active plugins. Shared hosting, no CDN.
Their TTFB averages 1.8 seconds on origin requests, not catastrophic, but meaningfully above the range that earns Google’s full crawl capacity. Googlebot visits the site, finds consistent but slow responses, and calibrates its crawl rate accordingly.
In practice, this may mean Googlebot visits 20–30 pages on a given crawl cycle when it could be visiting 80–100 on a faster host. New listing pages added on Monday might not be indexed until Thursday or Friday. A competing brokerage on faster managed hosting with a CDN has new listings indexed within hours.
For the real estate brokerage, this is not an abstract technical problem. Listings that are not indexed cannot appear in search results. Listings that appear in search results three days late have missed the window when buyers were actively searching for that property type and price range.
The Sitemap Is Not the Answer
A common response to this concern is: “I submitted a sitemap to Google Search Console, so Google knows all my pages.”
A sitemap tells Google what exists. Crawl budget determines how often and how thoroughly Google visits those pages.
Submitting a sitemap to a slow server does not increase how often Googlebot visits. It tells Googlebot which pages you want it to visit. Crawl budget constraints then determine how many of those pages actually get visited in a given crawl cycle. The sitemap is the request; crawl budget is the capacity.
High-priority pages on a slow server may still get regular crawls. Deeper pages, service area pages, blog archives, older product listings, location-specific content, are where budget constraints hit hardest. These are frequently the pages that have the most potential value for local and long-tail search, and they are the first to be under-crawled when server response times are slow.
What This Means Before Keyword Strategy Matters
Keyword research, content strategy, and link building are all downstream of the question of whether Googlebot is reading your pages. A well-written service page that targets a specific local keyword phrase cannot rank if it is only being crawled once every three weeks.
This is the upstream problem that most SEO agency conversations never reach. The conversation starts with: what keywords should we target? The prior question is: are the pages we already have getting fully indexed, and how often is Google revisiting them?
For multi-location businesses, for service businesses with large page counts, for any company that regularly publishes new content and needs it indexed quickly, server response time and crawl budget are foundational, not secondary considerations.
Checking your TTFB is not complicated. Tools like PageSpeed Insights, GTmetrix, and Pingdom all report it. The number to watch is origin TTFB. Under 200 milliseconds is good. Over 500 milliseconds starts to constrain crawl capacity. Over 1,000 milliseconds is a problem regardless of what else you do for SEO.
Fixing it typically involves infrastructure decisions: moving from shared hosting to managed hosting, implementing a CDN, reducing database query load on the origin server, or reducing the number of plugins making external requests on every page load. These are not always expensive changes, but they are infrastructure decisions, not content or keyword decisions.
iServU works with Tampa Bay businesses and remote companies to assess the full indexing picture: TTFB, crawl budget, sitemap configuration, and the resource load that is consuming Googlebot’s capacity without appearing in any Lighthouse report. Gabriel works the assessment directly, no account manager, no handoffs.
If you have more than 30 pages on your site and have never had a crawl budget audit, this is worth thirty minutes of your time. Free assessment available at iservu.com.
Sources
- Google Developers: Crawl Budget Management (2024, updated 2026). https://developers.google.com/crawling/docs/crawl-budget
- John Mueller / Google via Kwebby (2024). How Server Response Time Affects Google’s Crawling. https://kwebby.com/blog/how-server-response-time-affects-googles-crawling/
- Google Search Central Blog (2024). Crawling December: Resources. https://developers.google.cn/search/blog/2024/12/crawling-december-resources
- Google Search Central Blog (2024). Crawling December: CDNs. https://developers.google.cn/search/blog/2024/12/crawling-december-cdns